Chat
Talk to a running server
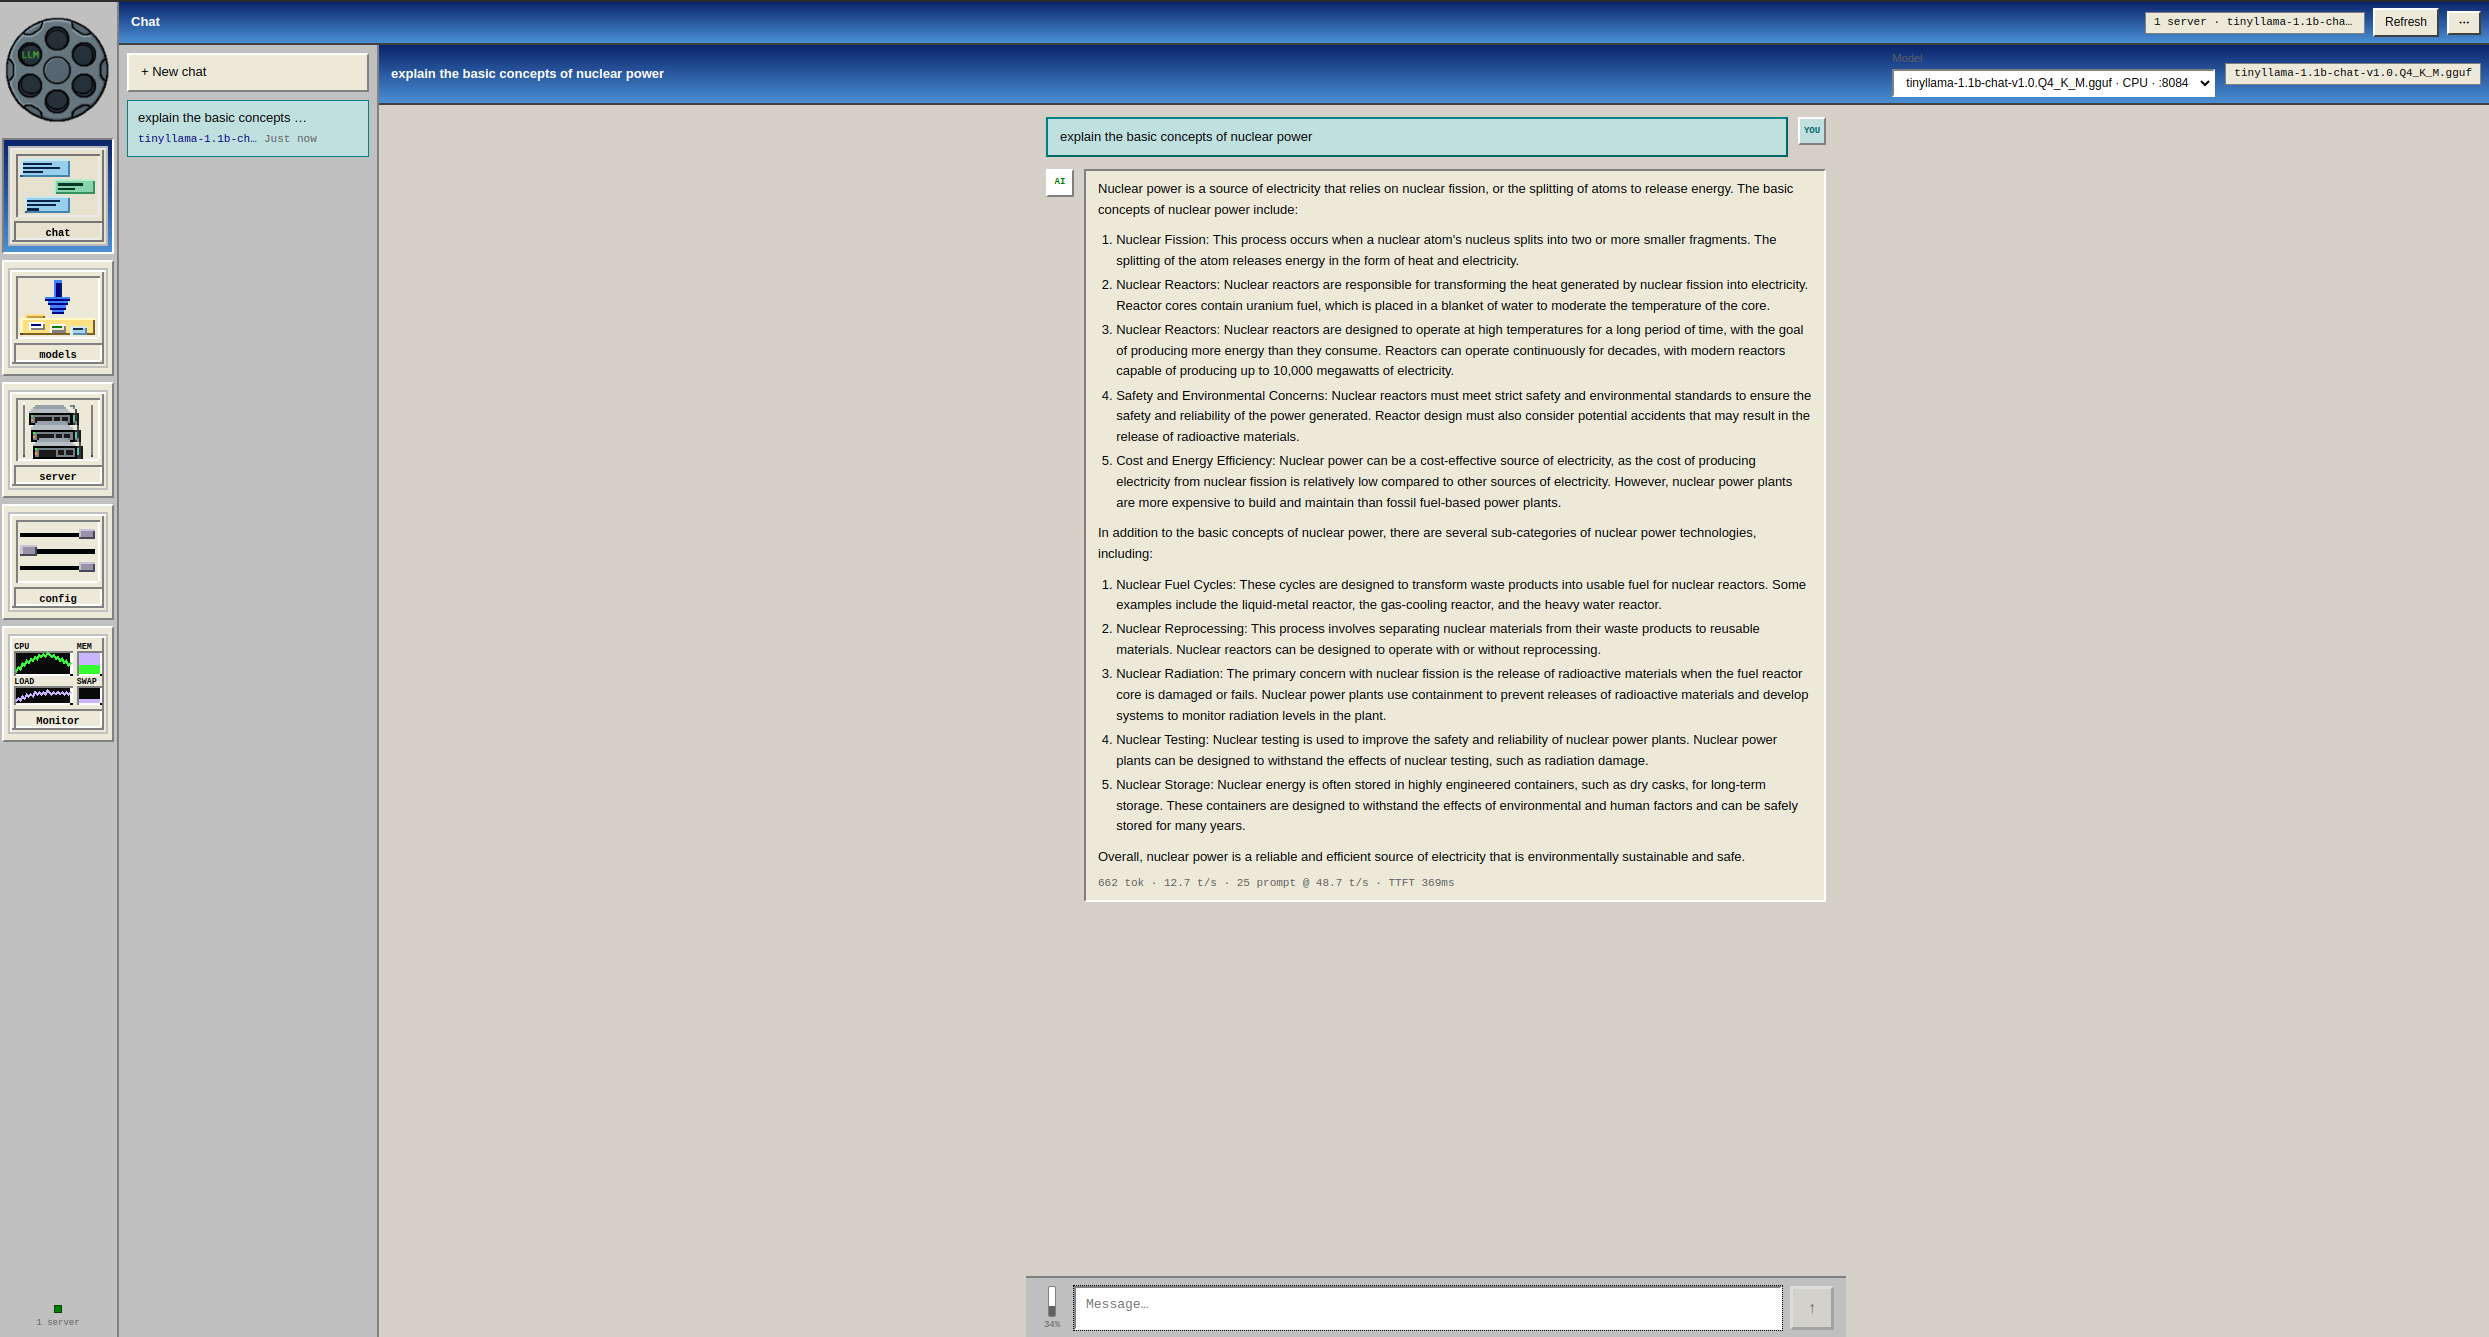
Multi-turn chat with markdown, KaTeX math, and reasoning traces when the model emits them.
Chat with your loaded models with a simple, lightweight chat interface. Load models with a setup server wizard. Download models. No telemetry. No metrics. Lightweight.
Multi-turn chat with markdown, KaTeX math, and reasoning traces when the model emits them.
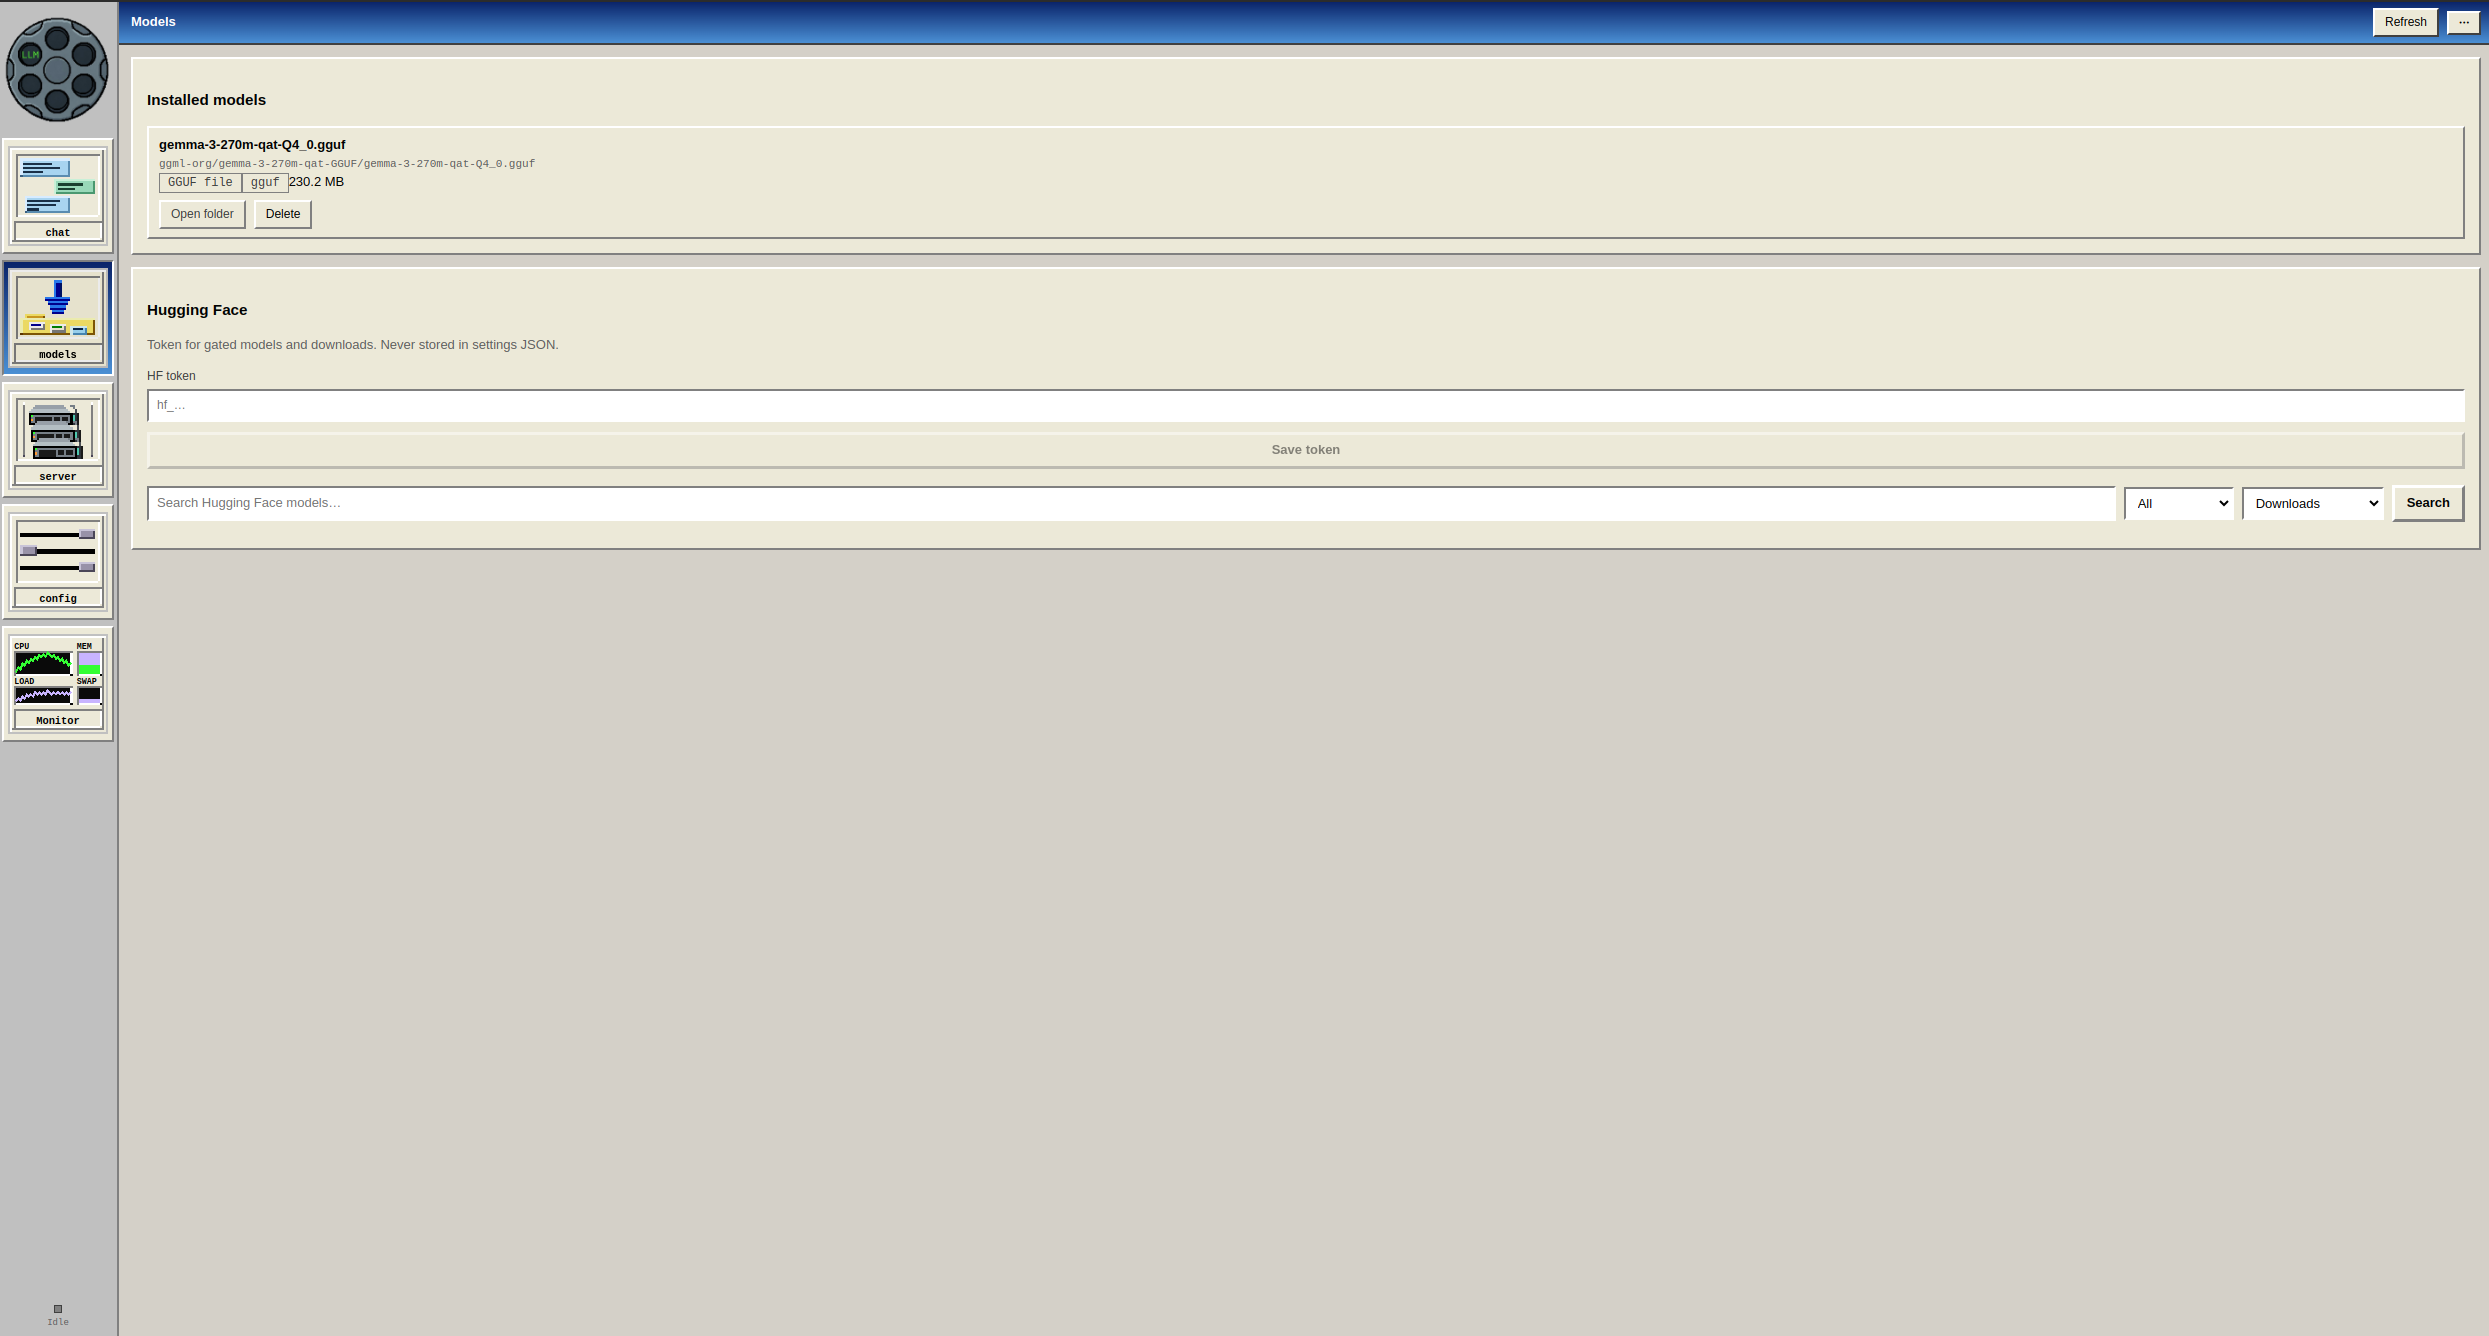
Installed GGUF on disk, plus hub search and download. The hub token is stored in settings.
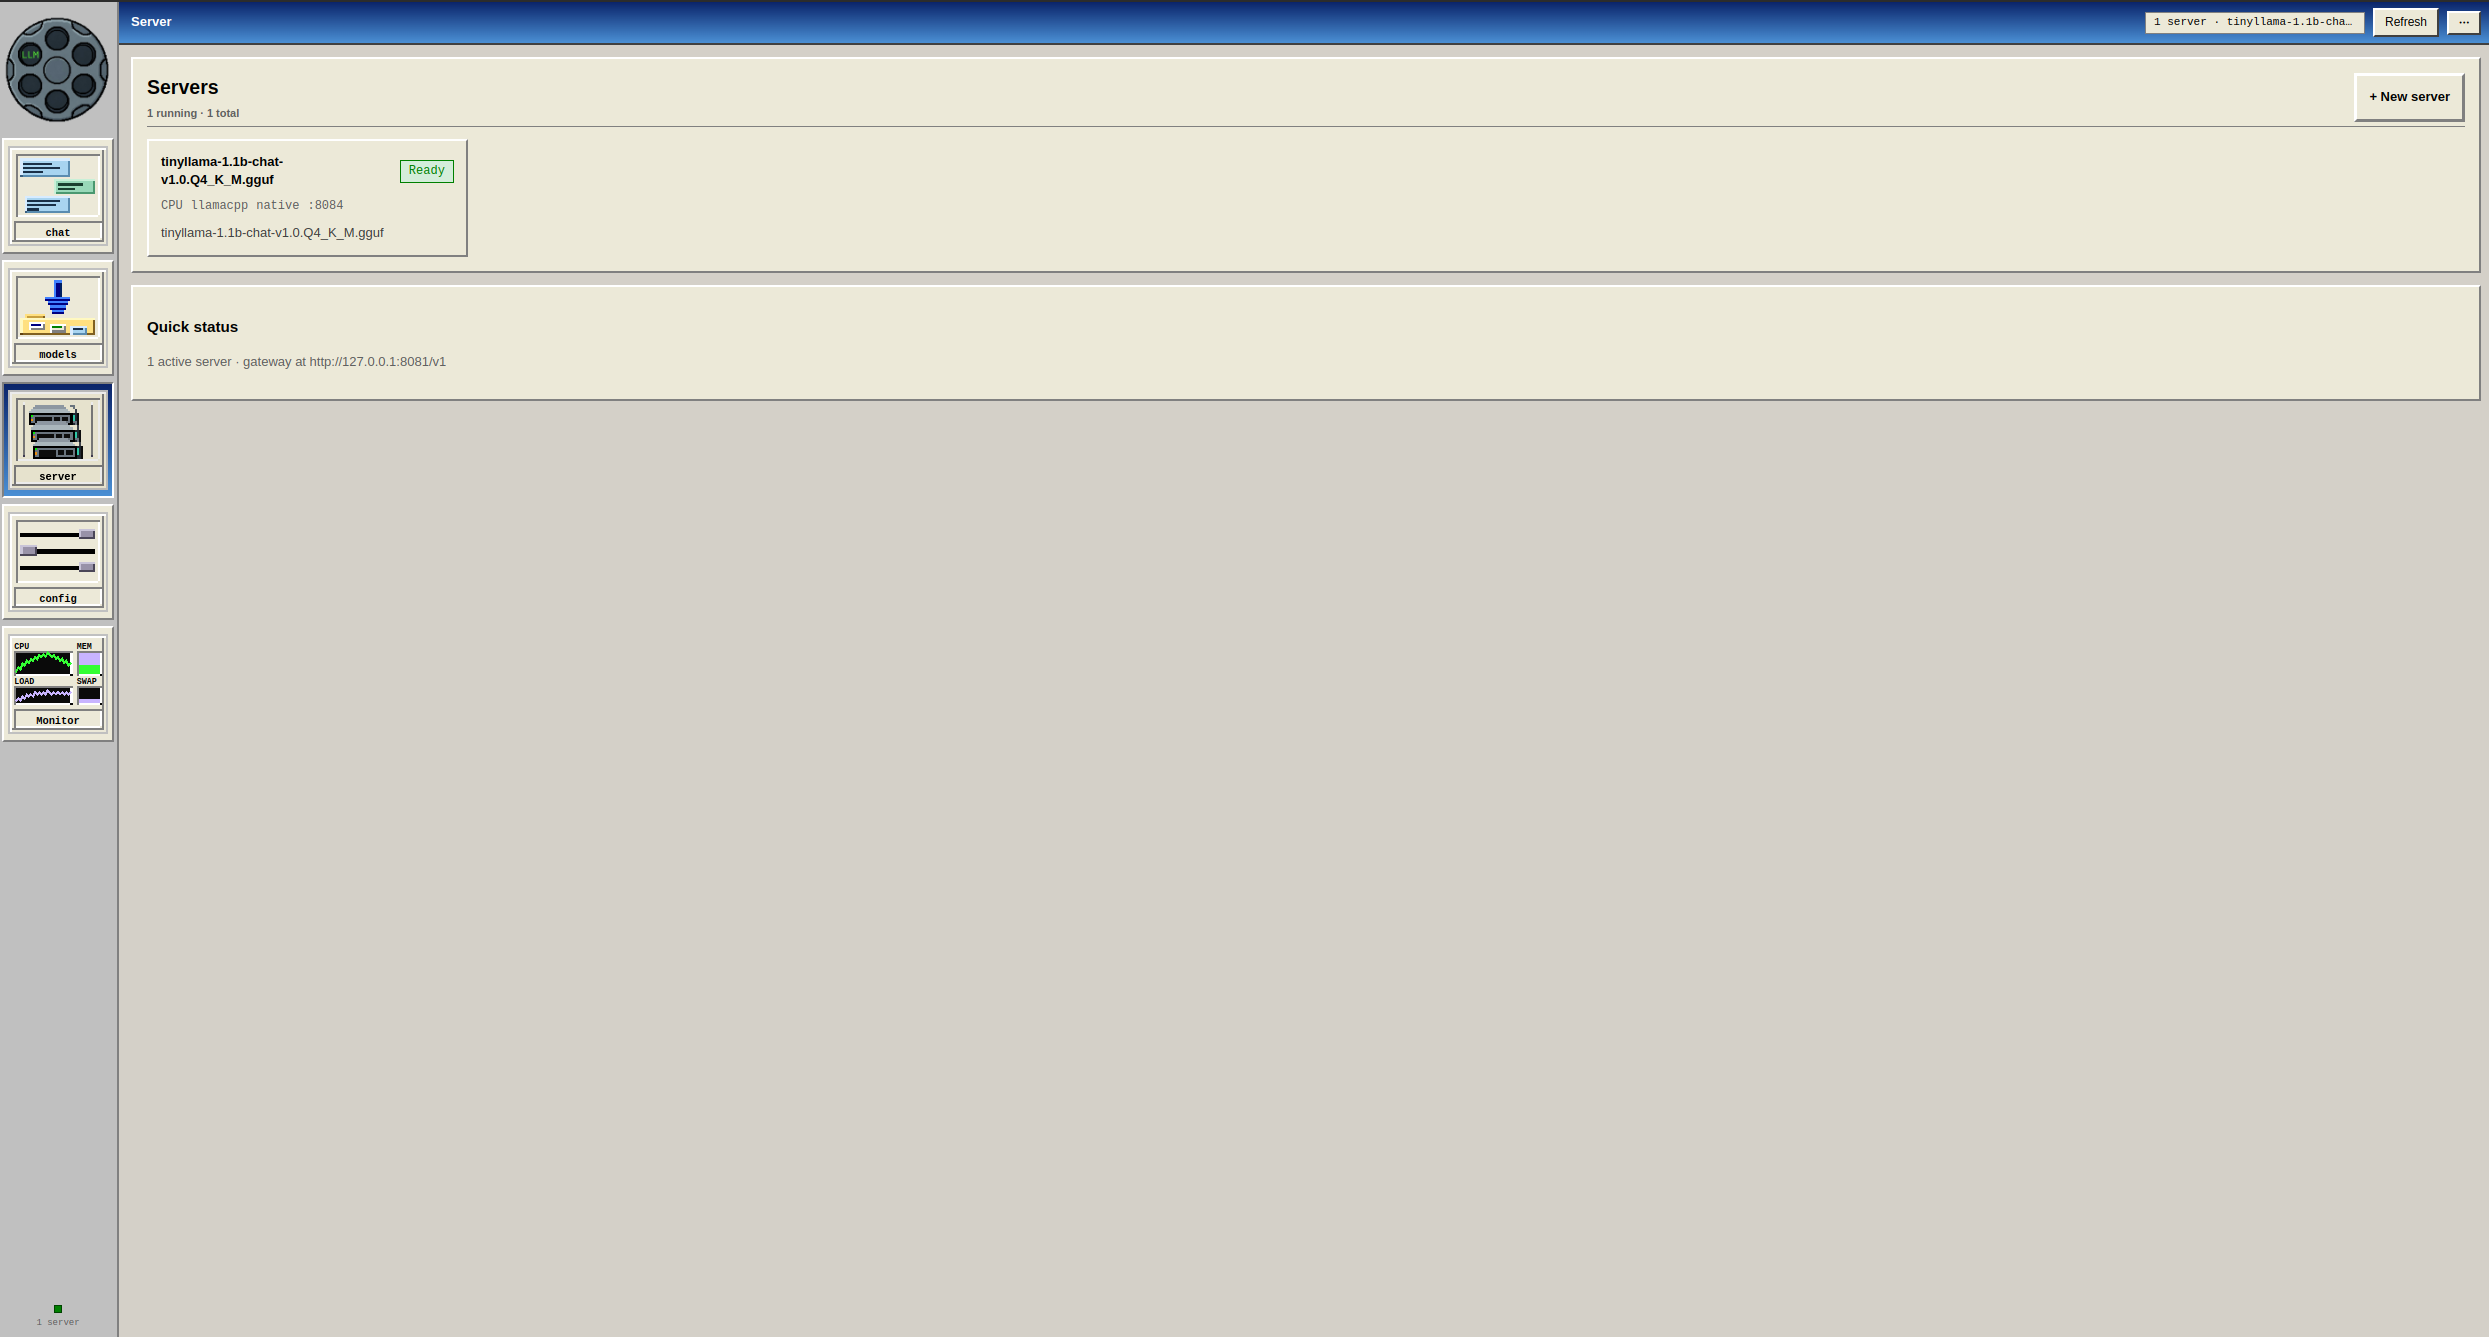
Create, load, and stop servers. Pin a GPU. New instances default to a native host process. Docker remains available.
Default context length, GPU layers, and KV cache. An OpenAI-compatible endpoint for other clients.
CPU, memory, disk, and swap. GPU and VRAM when the driver stack reports them.
The Electron shell is thin. llama.cpp and MLX download from GitHub releases, with a checksum, into the data directory.
Screenshots from the current desktop app.
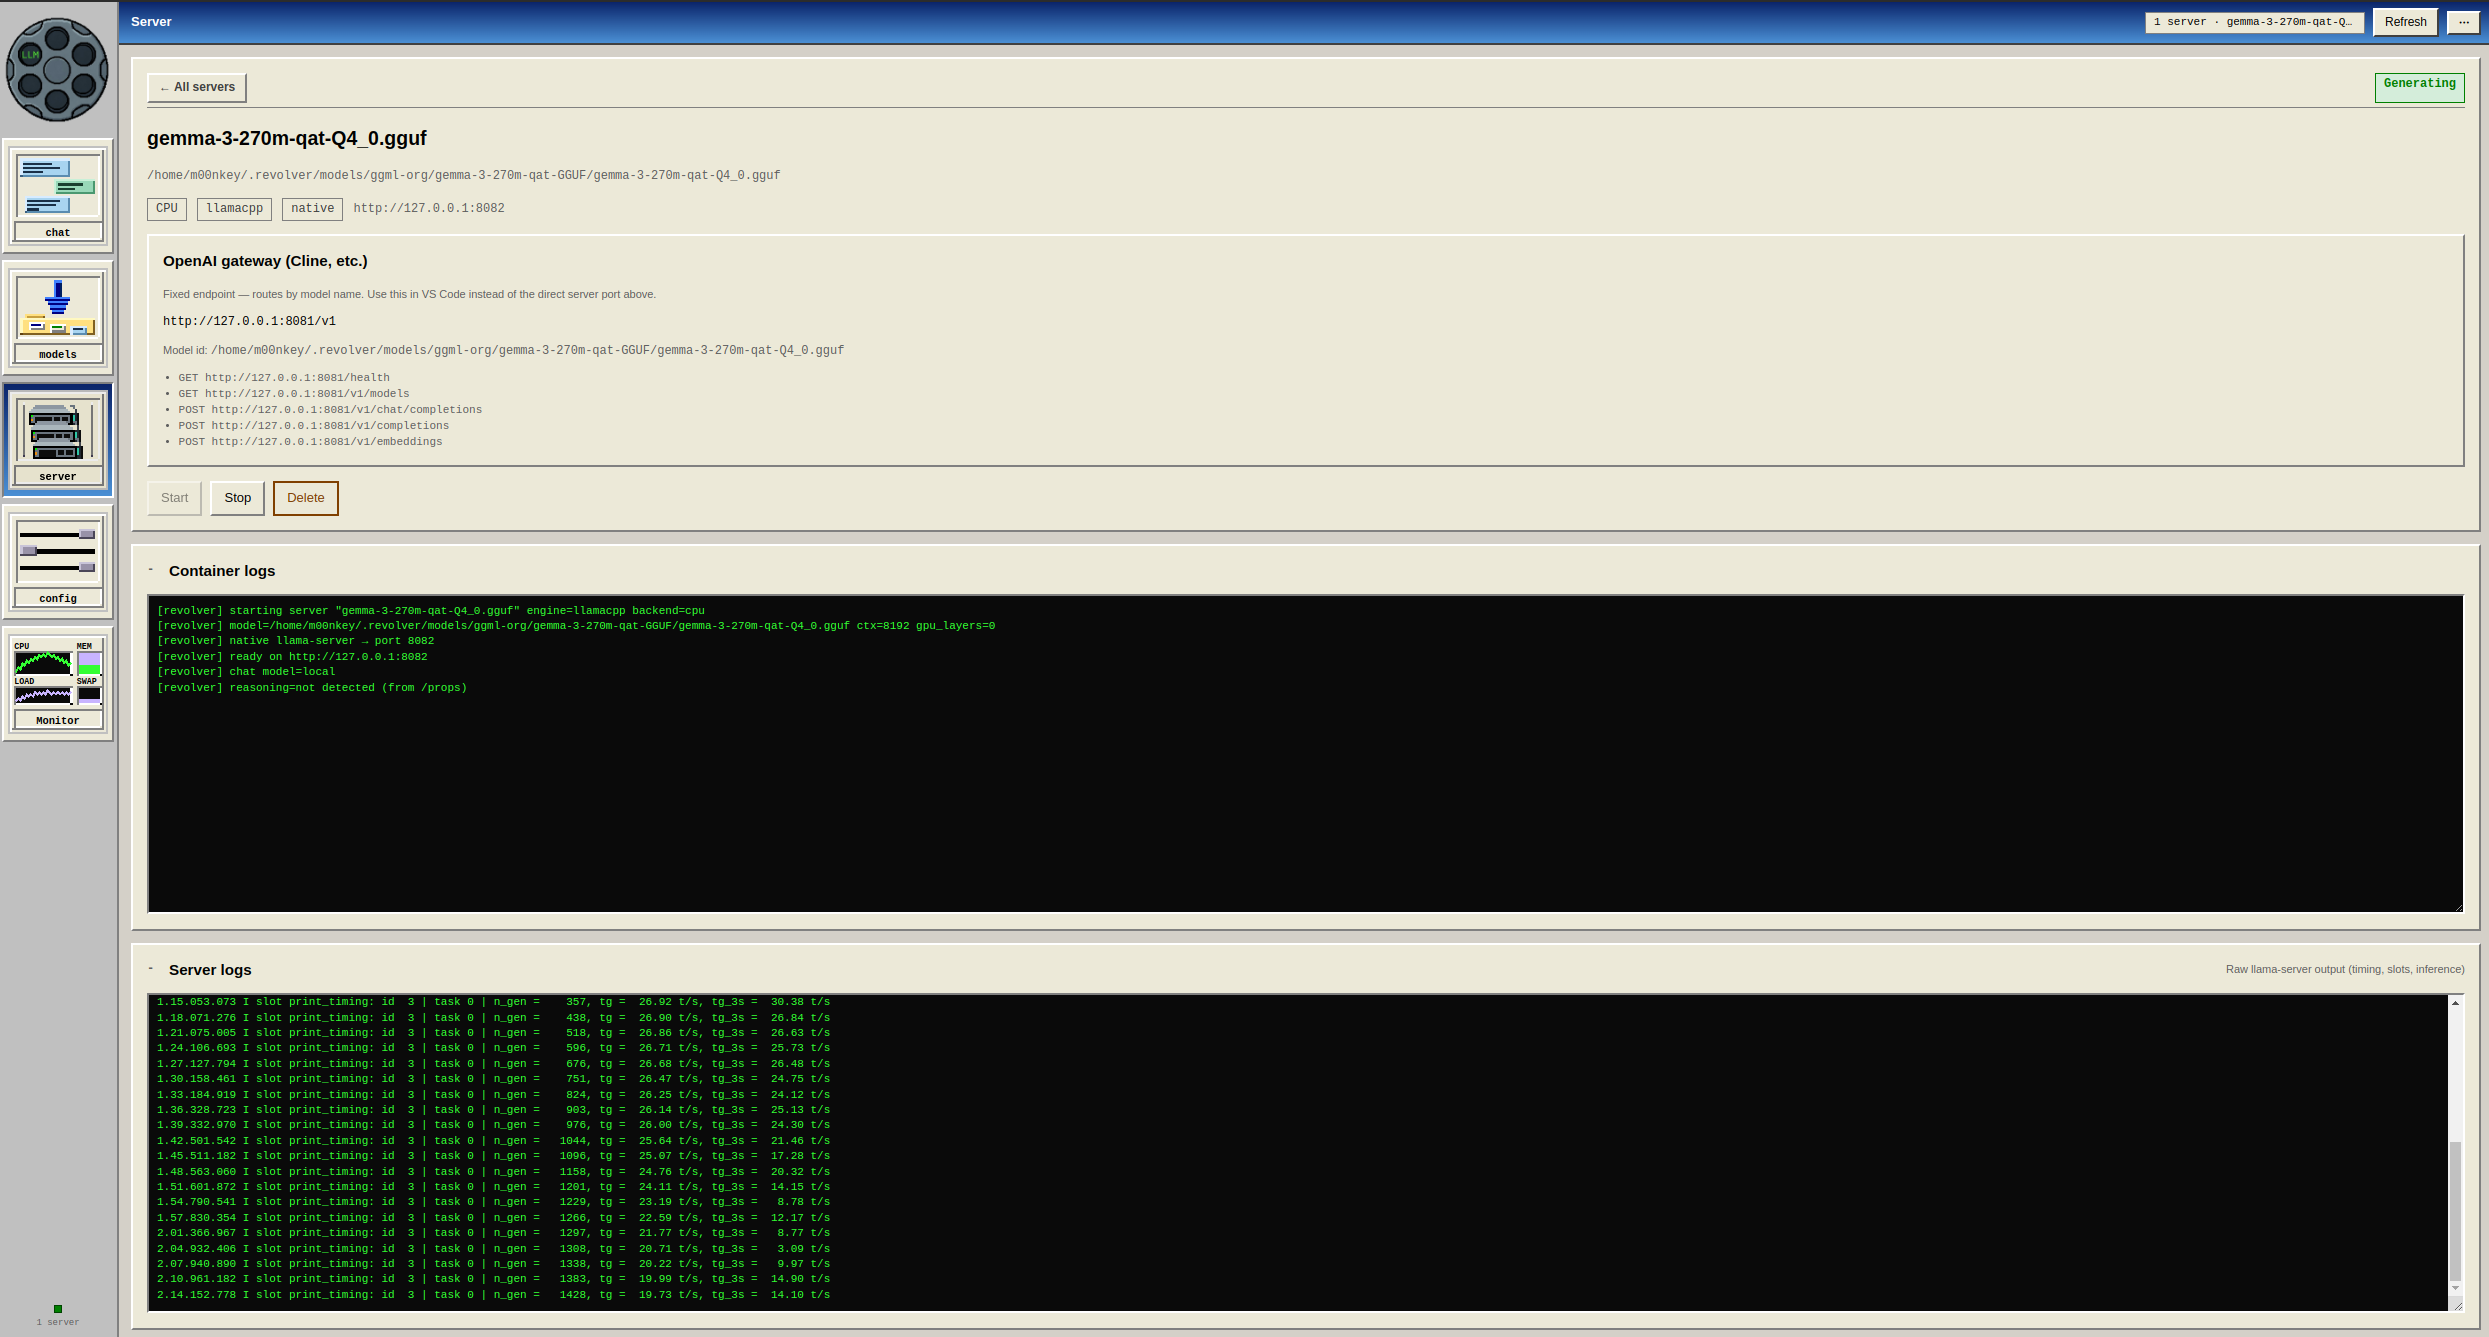
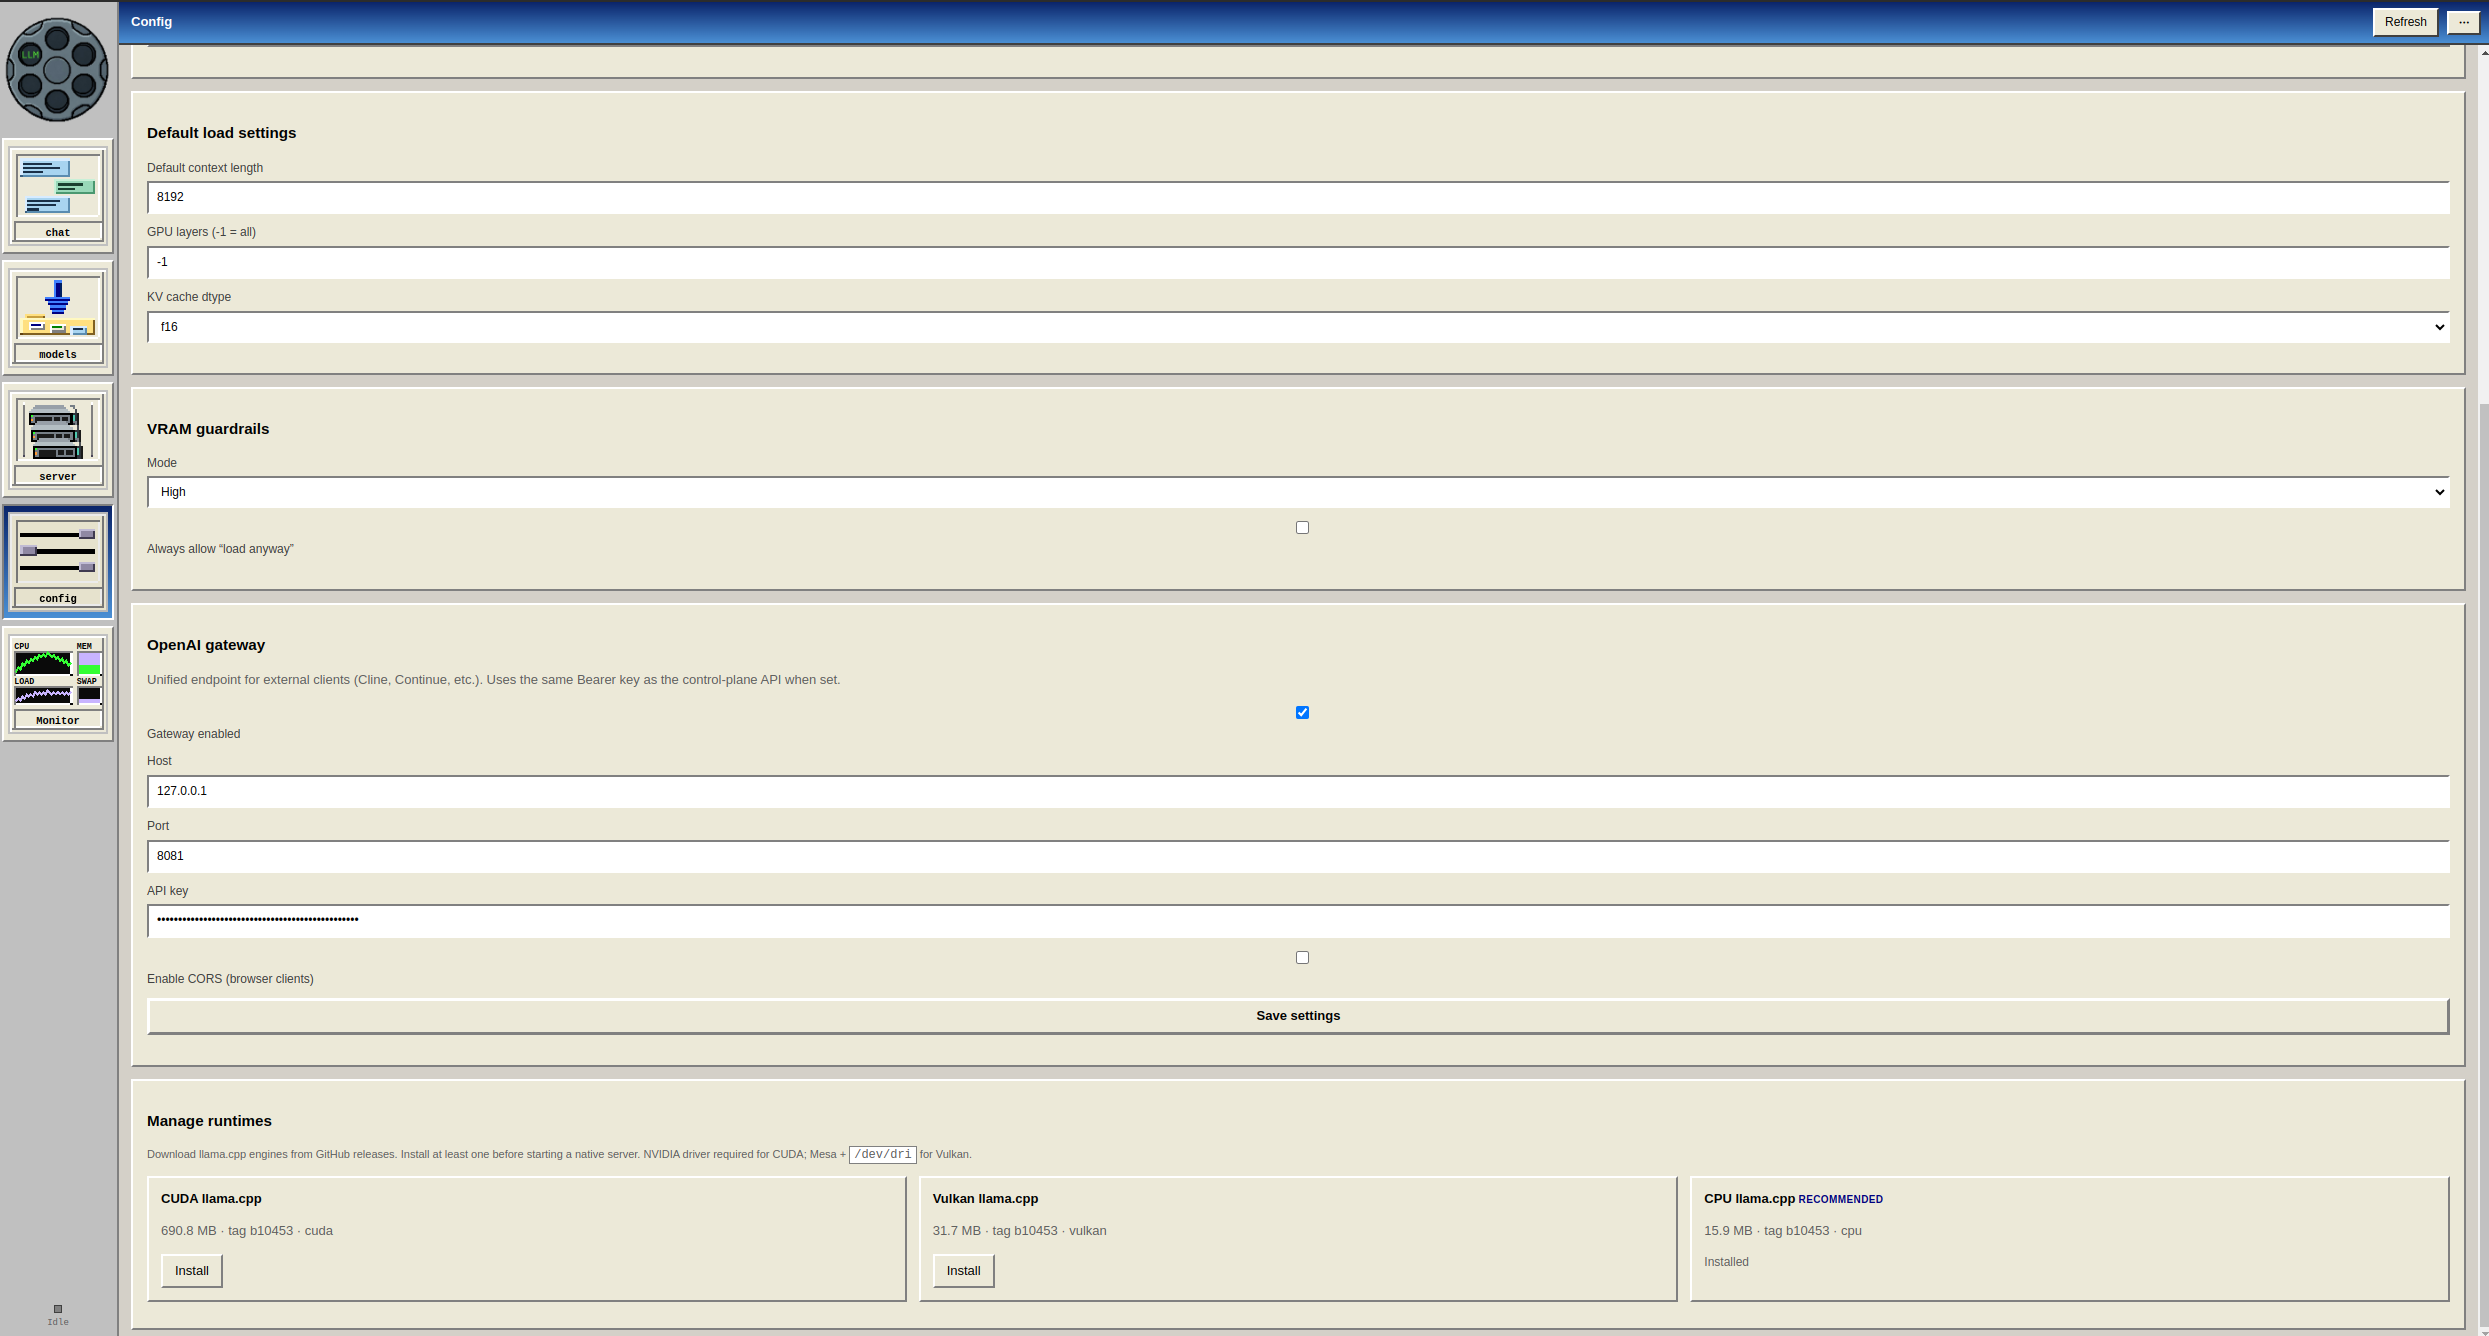
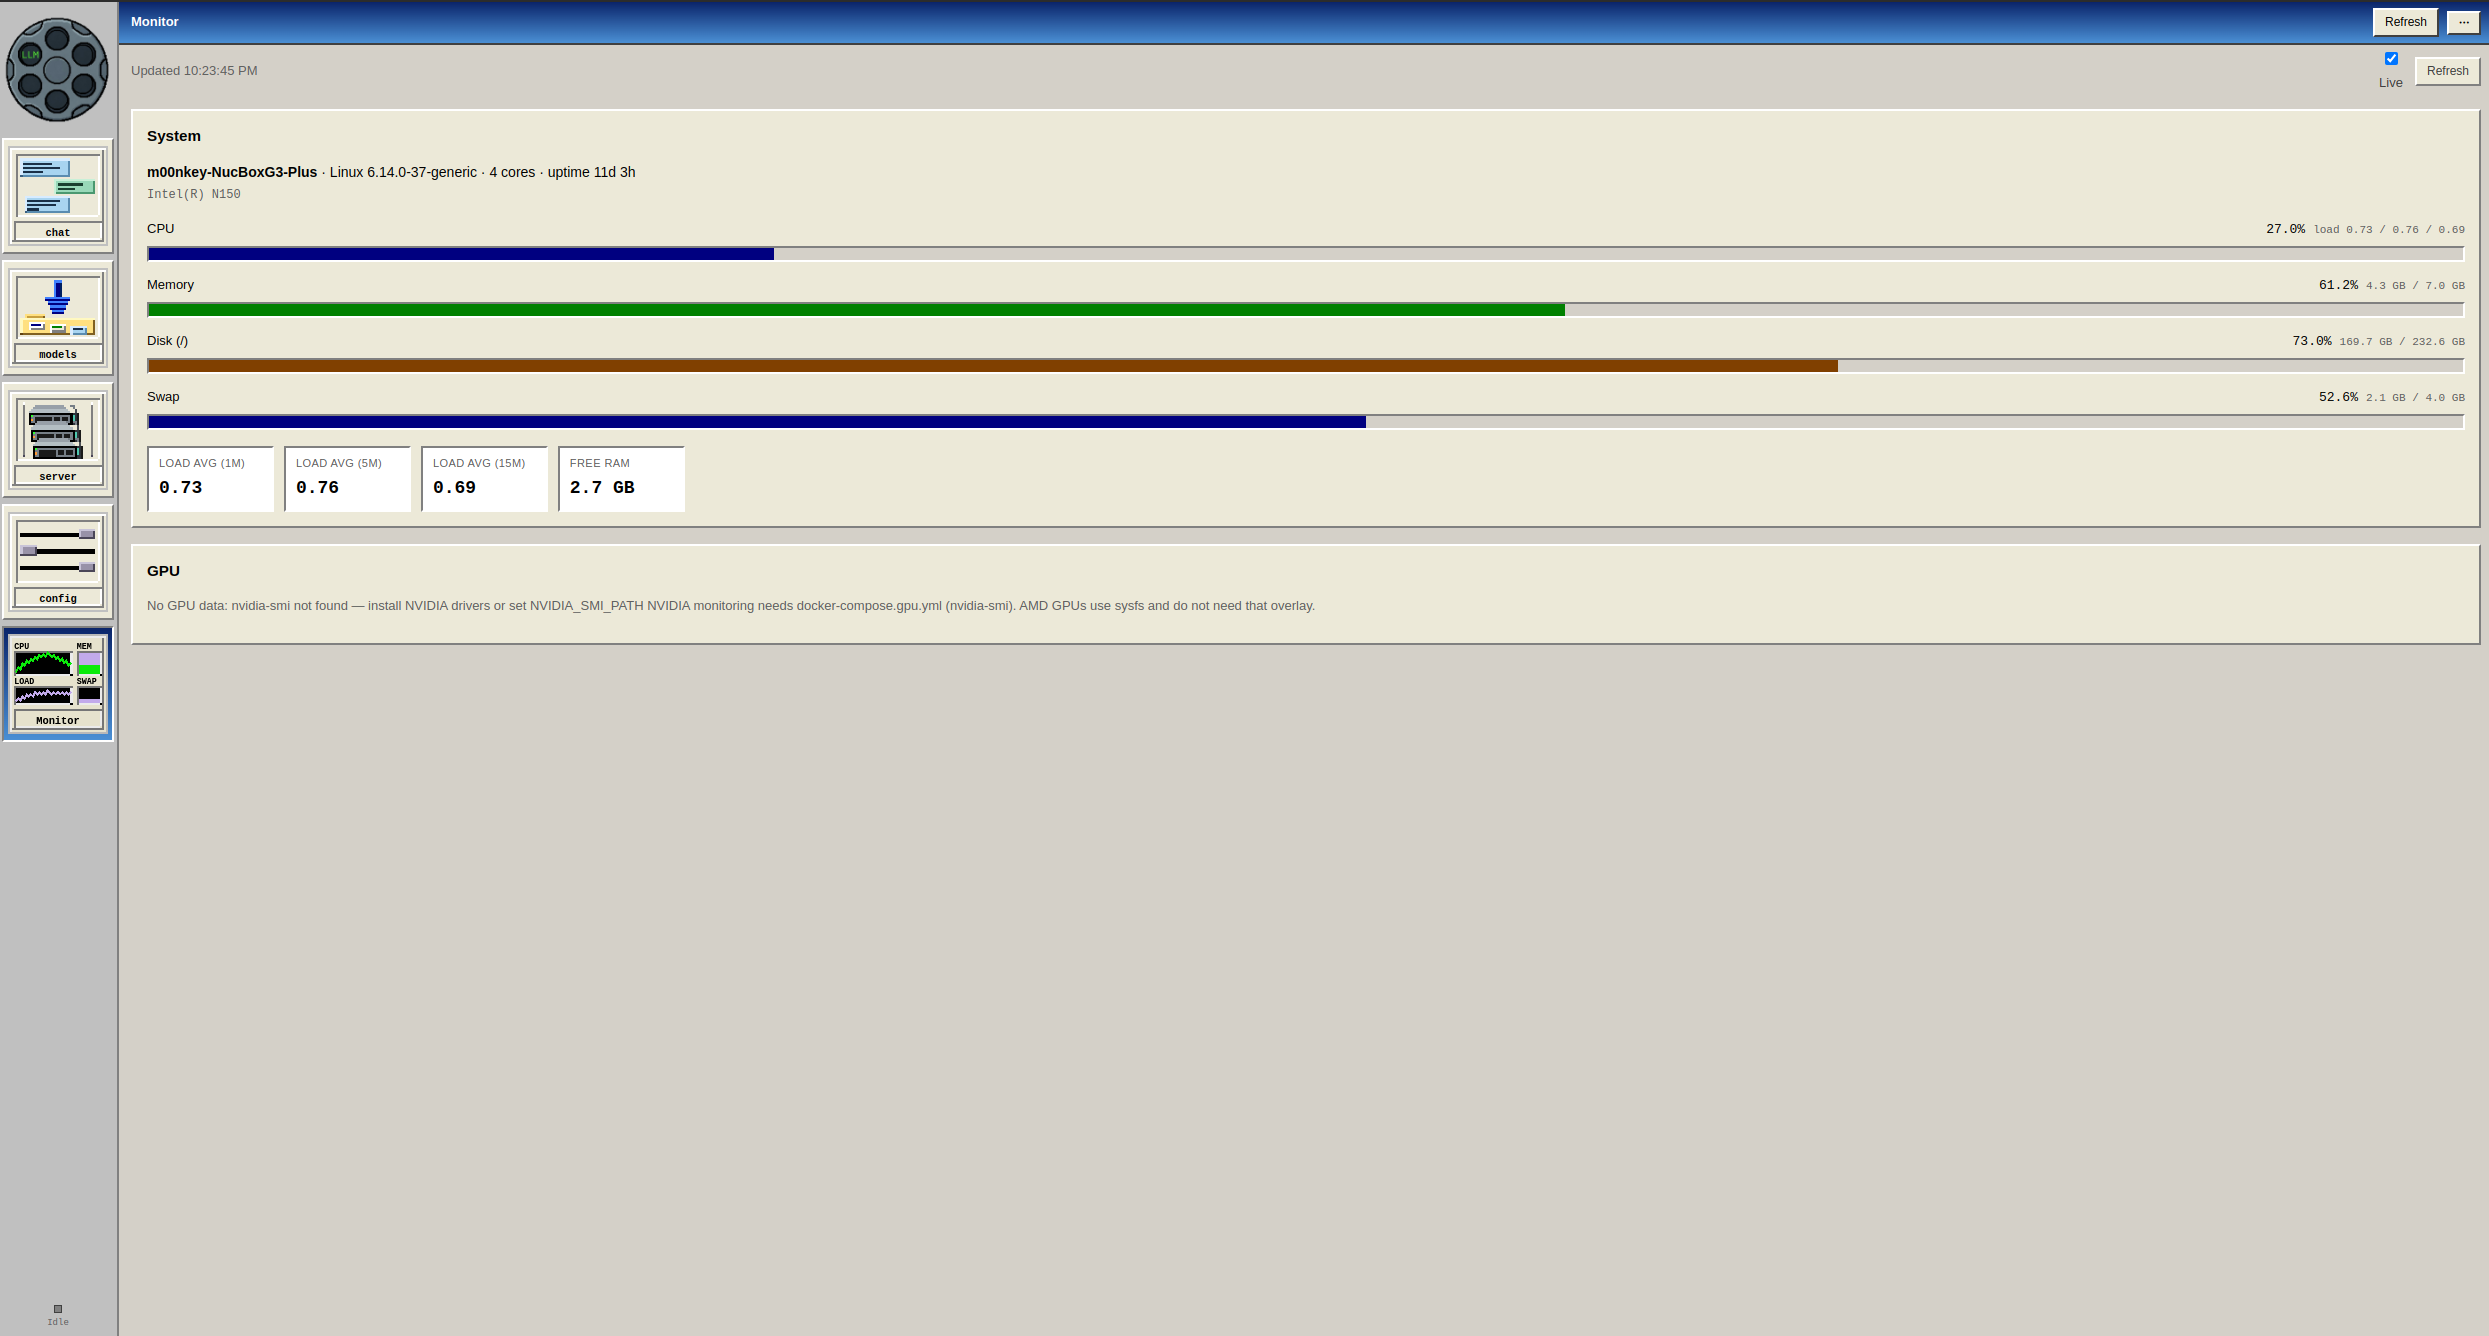
The current product is the Electron native app. Docker Compose is still available when you want a browser UI and container-only inference. Notes are in the dev log.
Desktop app. The main process hosts the control plane. New servers start a host llama-server. Runtimes download on first use. This is the default path.
nginx serves the UI on port 8080. The backend listens on loopback. Inference runs in containers through docker.sock. Native spawn is disabled.